pipeline red across the board because one disk filled up

cidisk-spacedocker29 replies · 767 views · started
  1. guys pls help every pipeline on our Jenkins agent satrted failing at the test stage. The error is basically no space left on device, and the monitoring shows this:
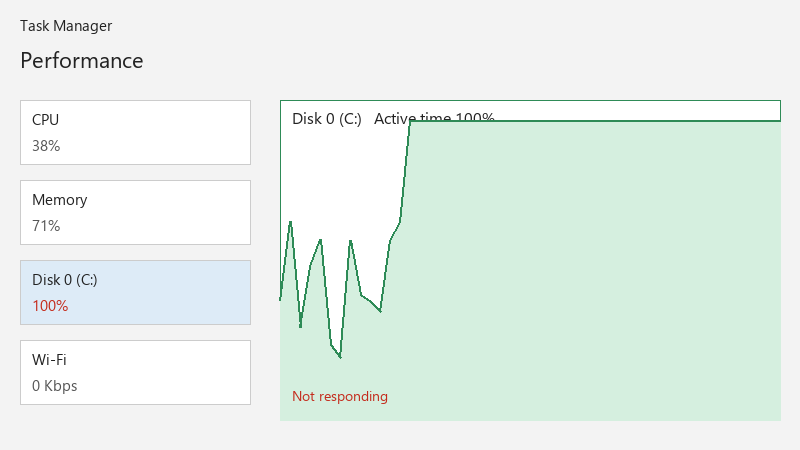
    Disk 0 (C:) Active time 100%

    Disk 0 (C:)   Active time 100%
    Not responding
    

    we never stored anything big on that machine. i delteed some old logs and freed maybe 2 GB, which was gone again after three builds. what is actually growing here?

    The runner builds maybe a dozen Docker images a day for a few repos. Nothing huge, I thought. Im starting to suspect something is cacihng aggressively behind my back. What are teh usual hiding spots on a build machine?

    6
  2. hmmmm quick q is Dockers data root on the same disk as the OS? ?

    2 0 helpful
  3. hmmmm not sure about that respectfully disagree, i tried that and it made ci worse but hey ymmv

    0 2 helpful
  4. yeahhh for me it was teh update. swapped it and boom, fixed. my laptop is officially haunted lmk how it goes

    0 5 helpful
  5. pro tip: write down what u change... i didnt and had to redo ci from scratch good luck man!

    5 0 helpful
  6. ok so package manager caches grow too: ~/.npm, ~/.cache/pip, ~/.m2, ~/.gradle. Either cap them, or put them on a separate volume so a bloated cache cant take down the system disk.

    0 1 helpful
  7. oh ive been there lol check per-job workspace folders: Jenkins keeps workspace/ per job and branch, GitLab runner keeps builds/ and cache/. old branch workspaces pile up. jenkins has teh 'Discard old builds' setting and the Workspace Cleanup plugin; GitLab runners can use docker executor volumes that get cleaned with clear-docker-cache. worked for me anyway 🤷

    5 0 helpful
  8. help!! i swear disk-space is cursed. this. so much this what am i doing wrong??

    1 2 helpful
  9. uhh wait does this also apply to disk-space?? ?

    1 4 helpful
  10. If du and df disagree, a process still holds deleted files open. Find them with sudo lsof +L1 or lsof | grep deleted. restarting teh process (often teh runner service or a log shipper) releases the space. lmk how it goes

    thinking

    2 0 helpful
  11. lol this thread is gold what am i doing wrong??

    0 14 helpful
  12. oof make it automatic: a sytsemd timer or cron that runs docker system prune -af --filter until=48h nightly, plus disk usage alerting at 80% sooo u hear about it before docker build breaks.

    6 0 helpful
  13. oh ive been there lol on build machines its almost always Docker... see exaclty how much:

    docker system df
    docker builder du
    

    Then clean safely with docker system prune -af --filter "until=72h" and docker builder prune -af... note -a also removes unused images, so the next build will pull again. good luck man!

    0 6 helpful

Reply to this topic

Sign in or create an account to reply.